
Counting Distincts and High Cardinality Aggregations: Designing Snowflake for Interactive Analytics
William McKnight & Jake Dolezal
When an analytics dashboard shows a broken tile instead of a number, someone in the business makes a worse decision or no decision at all. High-cardinality queries, like counting unique sessions or visitors, are one of the most common reasons interactive dashboards fail under load. This post tests whether Snowflake or ClickHouse keeps those dashboards running when it matters.
Every web analytics team eventually asks the same question: how many people actually showed up today? Answering it means running a query like this:
SELECT COUNT(DISTINCT session_id) FROM page_views WHERE event_date = CURRENT_DATE;
This query returns one number. It may even be the first tile on a web analytics dashboard because it answers the question: “How many unique sessions happened today?”
It is also a very expensive query you ask a database to run.
While it seems simple, calculating the result requires the engine to remember every distinct session it has seen in a window – say 50 million of them – and hold them in memory to know which ones it has already counted. Doing that fast, at scale, without falling over is exactly what a purpose-built interactive database engine is supposed to deliver. The size of the answer tells you nothing about the cost of getting it. That gap between a one-row result and a multi-gigabyte working set is where real-time, interactive engines can fall over.
The rest of the web analytics dashboard queries exacerbate the problem:
- Unique visitors today, this week, and over the trailing seven days.
- The top 100 pages by request volume, and the top 1,000 sessions by bytes transferred
- Traffic broken down by page, country, and device, with subtotals at every level
- Hourly unique sessions for the last seven days, refreshed every few minutes
- A sliding seven-day unique-visitor window, one value per day for the last month
These are the part-and-parcel queries of web analytics, product analytics, marketing intelligence, ad tech, security monitoring, and observability. Every one of them is a high-cardinality aggregation.
Why this scenario
Every ‘unique visitors’ or ‘distinct sessions’ tile on a dashboard is this query in disguise, and it’s often the one that determines whether that dashboard stays fast at scale or grinds to a halt. We chose this use case because it isolates specific, well-understood analytical challenges:
- The working set is invisible from the SQL. COUNT(DISTINCT x) looks identical whether x has 8 distinct values or 500 million. Nothing in the query text warns you what cardinality the data has.
- Cost scales with cardinality, not with data volume or result size. Doubling your rows might change little. Doubling your distinct sessions doubles the memory.
- It is the workload that often gets sized wrong. Teams provision for scan throughput and get surprised by aggregation.
- It is where in-memory architectures are supposed to be strongest. ClickHouse’s specialized hash sets and hash tables are genuinely excellent at this shape. If there were ever a workload where a fast in-memory engine should win outright, it is this one.
That last point drove the test design. This benchmark deliberately gives ClickHouse its best use case.
Three things that make this workload expensive
- Aggregation state scales with distinct values, not result set LIMITs. A COUNT(DISTINCT session_id) over 50 million distinct sessions returns one row and holds 50 million values. Limiting the result size does not help. A top 100 page ranking returns 100 rows and builds a hash table over 7.5 million distinct URLs first. The LIMIT is applied at the end. It saves you nothing.
- Wide GROUP BY and grouping sets multiply that state. GROUP BY session_id over 50 million sessions means 50 million live aggregate rows. Put an approximate distinct inside it and each of those 50 million groups carries its own probabilistic summary of the set. Add ROLLUP over two high-cardinality keys, or CUBE over four, and the engine materializes several of those tables at once.
- Approximation collapses the whole problem. A probabilistic summary is a few kilobytes regardless of whether it is counting a thousand distinct values or a billion. Swapping exact for approximate does not make the query faster. It only changes the memory profile from linear-in-cardinality to constant.
Architectural questions for high cardinality
- What happens when the aggregation does not fit? Every engine has a ceiling. When this ceiling is hit does the query get killed or slowed down?
- What is your memory limit?
- Where does the exact/approximate boundary sit in your workload? Most dashboard tiles do not need an exact count of unique visitors. Some do, like billing, compliance, and audit.
- Do you have a serving path for the lighter end of the query mix? A high-cardinality mix is not uniform. Some of these queries are sub-second and belong on a low-latency path while a few are genuinely heavy and do not.
Our Central Focus
We framed the following set of questions to test Snowflake and ClickHouse’s capabilities and performance:
- How large is the aggregation state? Distinct counts and wide GROUP BY size their memory to the number of groups, not the number of rows scanned. What does that come to, and can you predict it before the query runs?
- What does exactness cost? Exact COUNT(DISTINCT x) against its approximate counterpart on the same key at the same scale: the latency saved, the memory saved, and the accuracy given up.
- What happens when the state does not fit? Spill to disk or fail outright?
- Where does concurrency break it? One heavy aggregation may fit, but several arriving at once do not. At what point does each engine turn load into latency, and at what point into errors?
- What is the cost of a successful query? Throughput counted net of failures, at matched compute cost.
The Test
We built a test around website clickstream data. One row per event, with the visitor, the session, the page, the source IP, the country, the HTTP method and status code, the response time, the bytes sent, and a trace ID.
- 1.5 billion events. Over 0.5TB of raw data, three years of history (1,095 days), 150 million sessions averaging ten events each. Both engines loaded from the same parquet in the same S3 bucket.
- Realistic cardinality and skew. Page popularity follows a Zipf distribution: the single most-requested URL is 13.2% of all events and the top ten are 29% of the table. Source IPs are similar — the busiest one is 11.5% of events. Sessions, by contrast, are deliberately uniform and short-lived: the largest holds 122 events and essentially every session completes within a single day. That combination is what makes the aggregation memory of these queries unpredictable.
- Matched physical layout. For Snowflake, we used CLUSTER BY (EVENT_DATE, SESSION_ID). For ClickHouse, we used a MergeTree ORDER BY (event_date, session_id).
- Fourteen queries in four families, run round-robin. All fourteen queries return identical rows on both engines, with only platform syntax differences where the dialects genuinely diverge
High-cardinality distinct counts
- B2-A1: “How many unique visitors, accounts, countries and browsers did we see?”
- B2-A2: “Daily unique visitors, pages and requests for the last 30 days.”
- B2-A3: “How many distinct sessions were fast, medium and slow?”
- B2-A4: “Daily unique visitors for the last 90 days, approximately.”
- B2-A5: “Exact and approximate side by side, so the error is visible”
Wide GROUP BY
- B2-B1: “Which sessions consumed the most bandwidth?”
- B2-B2: “Top 1,000 sessions in the last 90 days, with last-seen date.”
- B2-B3: “Which pages get the most traffic, and how fast are they?”
- B2-B4: “For each session: page views, bytes, and how many distinct pages.”
Grouping sets and rollups
- B2-C1, C2, C3: “Traffic broken down by page, country and status — with subtotals at every level.”
Time-window aggregations
- B2-D1: “Unique visitors by hour for the last week.”
- B2-D2: “Rolling 7-day unique visitors.”
Compute Cost
We designed the test for an equivalent compute cost across the two platforms.
| ClickHouse | Snowflake | |
|---|---|---|
| Account Tier | Scale ($0.2985/8GiB/hour) | Standard ($2.00/credit/hour) |
| Compute | 2 replicas x 16 GiB each | 1 X-Small Interactive Warehouse |
| Interactive Usage | 32 GiB | 0.6 credits |
| Interactive Cost | $1.19/hour | $1.20/hour |
| Fallback warehouse | N/A | $0.033/min (For long-running queries) |
The Harness
A closed-loop, rising-concurrency sweep:
- Concurrency levels 1, 2, 4, 8, 16, 32. At each level, that many simulated users run the query mix simultaneously, round-robin, with no think time. Each issues its next query the instant the previous returns. We ran the queries as a deterministic round-robin to ensure equal distribution of the queries.
- 600 seconds per level. But in-flight queries going past the deadline were allowed to finish.
- Metrics captured. Attempts, errors, error rate, QPS, and p50 / p95 / p99.
How to Read the Results
Below are the common ways to measure the results and that Error Rate is the only one that matters when you have high failure rates:
- Latency. Comparing p95 across engines is only meaningful when both completed the same queries.
- Throughput. Our harness counts throughput as completed queries per second, so failures are already excluded. However, throughput rewards an engine for failures and is not a measure of getting more work done.
- Error rate. This is the only metric that matters when you have high failure rates (as ClickHouse does). A query that fails returns nothing. It does not contribute to throughput, and its latency is not worth measuring. When two engines complete different fractions of the same workload, they cannot be compared.
This is why the results below emphasize completion over speed. The question that separates these two engines on this workload is not how fast a query runs but whether it runs at all.
Results
The only useful performance comparison between the two engines are the single concurrency results (c=1) because while Snowflake completed 100% of the queries across all concurrency levels, ClickHouse did not. ClickHouse also failed on query B2-C2 at c=1 even though the measured peak memory of 13.9GiB did not exceed a single replica’s memory of 16GiB. This is likely because ClickHouse reserves 10% of RAM for itself, so the usable ceiling is closer to 14.4 GiB, not 16. The recorded 13.9 GiB peak was probably less than what the query needed. It’s probably where it was standing when the next allocation would have overshot. If at 13.9 GiB, it requested another 2.00 GiB chunk, it would have gone over the ceiling and probably triggered the out of memory (OOM) error.
With no concurrency and no timeout, running the mix sequentially, Snowflake was faster on 13 of the 14 queries, from 1.4x to 109x. The exception is B2-C3, where ClickHouse is 1.4x faster. The CUBE over three low-cardinality dimensions is a moderate-cardinality shape where a specialized in-memory engine should win.
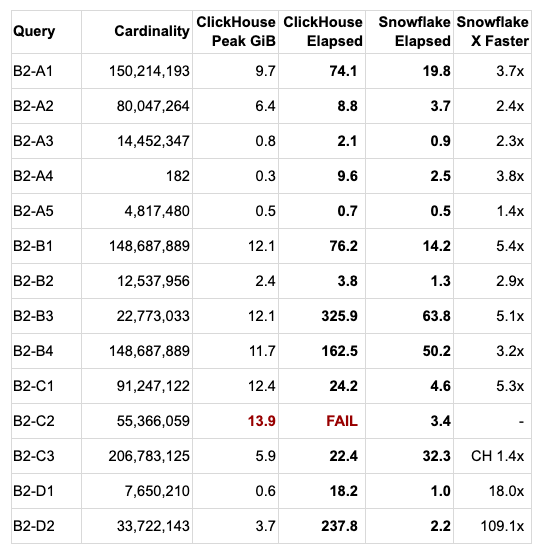
Table 1. Query run times (in seconds) at single concurrency. “Peak GiB” is the ClickHouse metric of peak memory. Snowflake does not have an equivalent metric.
Across the full sweep (fourteen queries at six concurrency levels) Snowflake returned an error rate of zero in every test. ClickHouse, at matched memory, did not:
| Concurrency | ClickHouse Error Rate | Snowflake Error Rate |
| 1 | 8% | 0% |
| 2 | 8% | 0% |
| 4 | 9% | 0% |
| 8 | 24% | 0% |
| 16 | 58% | 0% |
| 32 | 90% | 0% |
Table 2. Cumulative error rates over each concurrency run
Over the whole run ClickHouse failed 73% of attempts with spilling enabled. Every failure was OOM MEMORY_LIMIT_EXCEEDED.
Sorting the fourteen queries by the peak memory ClickHouse required produces a gradient of error rates as peak memory and concurrency rise.

Figure 1a: ClickHouse error rates by query for each concurrency run. The table is sorted by the “peak GiB” metric, which is ClickHouse’s reported peak memory during the c=1 run.

Figure 1b: Snowflake’s error rates by query for each concurrency run. Snowflake does not have a “peak memory” metric, so the query list was sorted by aggregate state cardinality.
Looking at some of the more problematic queries on ClickHouse:
- B2-B3 spilled 17.87 GiB to disk and took 326 seconds, against Snowflake’s 64 seconds. By concurrency 16, spill=on is failing 58% of queries, and by 32 it fails 89.5%. Spilling buys headroom at one user but then surrenders it under load, because each spilling query holds memory longer and fewer of them fit at once.
- B2-C2 fails under every configuration we tested. ROLLUP over page_url and source_ip (22.5 million by 75 million distinct values) peaked at 13.9 GiB. It failed at every concurrency level on ClickHouse. Snowflake returns it in 3.4 seconds.
Snowflake also spilled but finished anyway. Snowflake is not immune to the memory pressure, but it handles it differently. On the same workload it spilled between 2.7 and 7.1 GiB to local storage on B2-C3, B2-C2, B2-C1 and B2-A2. It never escalated to remote storage, and it never failed a query. The fallback mechanism is the differentiator. Snowflake’s Interactive warehouse enforces a five-second per-query ceiling. Anything exceeding it is transparently retried on a standard warehouse. That is an architectural difference this test demonstrates. Both engines hit the same wall. Snowflake converts the overrun into a result. ClickHouse converts it into a failed query.
Lessons Learned
- The SQL does not tell you what the query costs. COUNT(DISTINCT session_id) is identical whether the column holds eight values or 150 million. In this mix, peak memory ranged from 0.3 GiB to 13.9 GiB across queries that look comparably innocuous. Aggregation state is a property of your data, and it is invisible to most analysts writing queries.
- Spilling is a low-concurrency reprieve, not a safety net. With spilling off, five queries failed even at a single user. Turning it on rescued four of them – ClickHouse writes an intermediate state to disk instead of giving up. Any engine whose overflow strategy is “write to disk and keep going” should be tested at load, not at rest.
- Graceful degradation is the difference between a result or none at all. Snowflake’s fallback mechanism is why the error rate is zero. Architecturally, this is an important feature that ClickHouse does not have.
- Tuning burden compounds; it doesn’t disappear. Every ClickHouse failure above is fixable in principle, but each fix is query-specific and has to be reapplied every time a dashboard adds a tile or a filter changes the access pattern. Snowflake completed this entire sweep unmodified, on the smallest interactive warehouse it offers. The advantage is that Snowflake didn’t require rewriting SQL, restructuring the schema, or knowing in advance which query would need it.
Conclusion
This benchmark ought to give ClickHouse its best case. High-cardinality distinct counting and wide GROUP BY are exactly the shapes an in-memory columnar engine with specialized hash tables should dominate. However at low concurrency, only a few queries are competitive with Snowflake’s performance. And even at low concurrency, Clickhouse is competitive with Snowflake on only one query.
At 1.5 billion events and cost-matched memory, that advantage did not survive a high cardinality aggregation state. ClickHouse failed 73% of the workload. One query with a rollup over two high-cardinality keys could not complete. Snowflake completed all queries at every concurrency level from 1 to 32, with an error rate of zero, on the smallest warehouse it offers.
The difference is not raw speed. Both engines encountered the same memory wall on the same queries. Snowflake spilled over 7 GiB on the heaviest one. The difference is what happens at the engine’s boundaries. Snowflake’s Interactive warehouse bounds latency at 5 seconds and hands anything longer to a standard warehouse, converting overload into an answer. ClickHouse is bounded by the memory of a single replica and returns a MEMORY_LIMIT_EXCEEDED error.
If your dashboards are timing out or throwing errors under load, that’s the question worth asking your vendor: what happens when the aggregation doesn’t fit? For a dashboard, a slow tile is an annoyance, but a broken tile is an incident, and that difference comes down to architecture, not tuning. If distinct counts and large aggregations are pushing your dashboards to their limits, try Snowflake Interactive Analytics. Check out the documentation to get started.
